YIFAN WANG · LDN --:--
LocLondon
SchoolUCL · MSc AI for Healthcare
FocusReliable AI
Year2026
AI Systems & Reliability · Multi-agent · Interpretability

Yifan Wang

Reliable AI, measured — from agents to internals.
Yifan Wang — Barcelona
YIFAN WANG · 2026
BARCELONA· FR
“ Never be a boring person.
§ 01 · About
01 / DRIVERS

Robot APIs, synthesized.

Auto-Adapter turns MJCF/URDF specs into reusable Python drivers, verified against MuJoCo physics state.

02 / INTERP.

VLA failures, mechanistically.

SmolVLA on LIBERO. Predicting manipulation failure from internal activations before the robot moves.

03 / REASONING

Reward-guided medical QA.

DPO + process reward models + retrieval. Six controlled configurations isolate each contribution.

G6
04 / GTM AGENT

GTM analysis, agentic.

A four-module market-research pipeline with chat edits, cascade updates and a three-column UI.

§ 02 · Education

From electronic engineering to artificial intelligence.

MSc · Artificial Intelligence for Biomedical and Healthcare 2025.09 — 2026.12

University College London

UCL · Bloomsbury QS World #9 MSc Artificial Intelligence for Biomedical and Healthcare
/ Core modules
Reinforcement Learning Deep Representation Learning Natural Language Processing AI Interpretability Probabilistic Modelling
London — UCL
London · 2025
BEng · Electrical & Electronic Eng. 2021.09 — 2025.07

University of Nottingham

UoN · Nottingham QS Top 100 BEng EEE
/ Core modules
Artificial Intelligence Robotics & Control Digital Communications Engineering Software Design
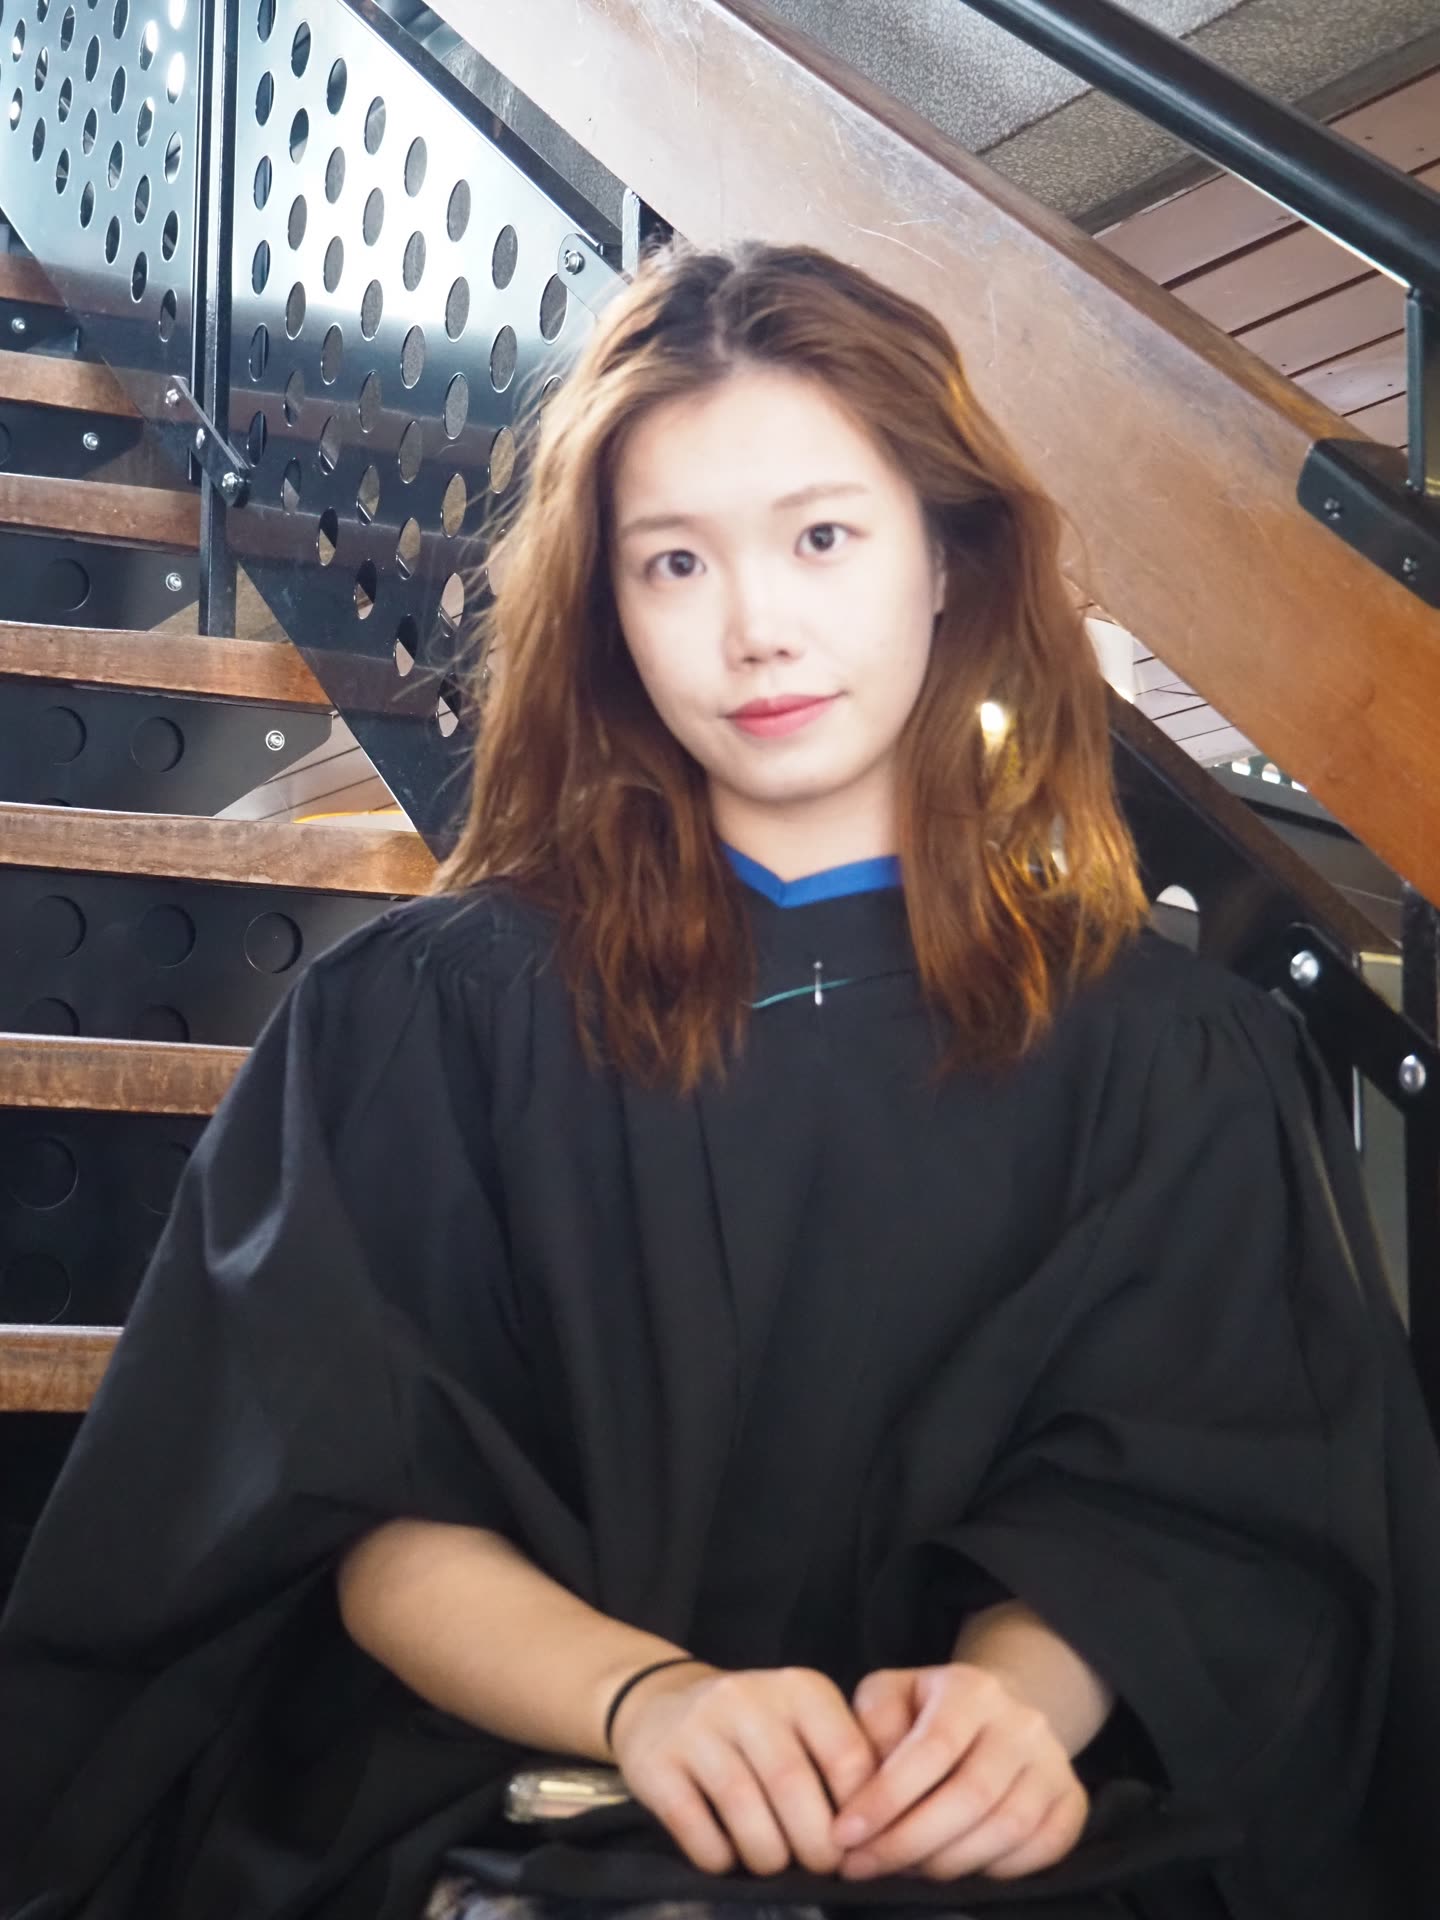
University of Nottingham — graduation
Graduation · 2025
§ 03 · Selected work

Four projects, one thesis — verify everything.

01/04
Research · Embodied LLM agents

Auto Adapter.

Physics-in-the-loop robot driver synthesis from MJCF/URDF for tool-using agents.
Type Paper
Role Robot Driver Synthesis
Period 2026 →
Stack MuJoCo · MJCF/URDF
Problem → Build

Tool-using LLM agents usually assume the robot already exposes a Python driver: move_cartesian, get_ee_pose, gripper_close. Auto-Adapter gives the agent that missing layer too: read MJCF/URDF, synthesize a reusable driver, and revise it against MuJoCo physics until the harness passes.

Architecture
FIG. 01a
Five-phase driver synthesis · physics-in-the-loop
robot specification MJCF / URDF joints · links · limits STUDY study.json GENERATE write driver revise ≤22x VALIDATE fresh sim EXPORT artifacts DEMO agent calls API DRIVER API move · pose · gripper PHYSICS CHECK qpos · xpos · contacts BENCHMARK 8 robots · 13 tasks $2.98 ± $0.84 · 7.8 ± 1.6 min · SO-101 reach/pick 100%
Auto-Adapter is a five-phase LLM-agent pipeline: Study reads the robot spec, Generate writes the driver, Validate re-checks it in a fresh MuJoCo simulator, Export bundles a reusable API, and Demo lets a downstream agent call it. The key verifier is not text output but post-step physics state; across eight robots, onboarding averaged $2.98 and 7.8 minutes.
02/04
Holistic AI · Interpretability

VLA Interpretability.

Predicting manipulation failure from activations — before the robot moves.
Org Holistic AI
Role Research Intern
Period 2026 →
Stack SmolVLA · LIBERO
Question

When a Vision-Language-Action policy fails under visual perturbation — where, inside the model, does the failure originate?

Approach

Perturb the scene. Trace internal activations across the model's components. Compare success and failure trajectories. Localise the failure stage — then intervene.

FIG. 02a
Perturbation-conditioned activation analysis
scene CLEAN PERTURBED smolvla · internals Vision encoder Language-vision bridge Cross-attention State integration Action expert activation traces compare LOCALISE FAILURE where in the stack does the signal diverge? → intervene feature steering · SAE
The core method, in three moves: perturb · trace · localise. The goal isn't to confirm a failure — it's to find the moment inside the model where the failure becomes inevitable, and to intervene before the action loop runs.
03/04
UCL COMP0087 · Team

DPO & Process Reward Models.

Retrieval-augmented reasoning with verifier-guided medical QA.
Type Team · UCL
Role LLM · RAG · Reward
Period 2025.10 →
Question

Are policy optimisation and inference-time adaptation competing methods, or do they complement each other in medical QA?

Methodology
FIG. 03a
Two-track framework · training × inference
Training-time · policy optimisation Base policy Llama-3.1-8B Generate N traces CoT samples PRM score medprm-v1.0 Chosen / rejected preference pairs DPO fine-tune → improved policy π* π* Inference-time · retrieval + verifier-guided selection PubMed retrieve Rerank cross-encoder Clean Llama-3.2-3B Generate K traces w/ DPO policy π* PRM score per-step SC + RM → final answer
Two parallel tracks. DPO improves the policy that generates answers. Retrieval + cleaning + PRM-guided selection picks among them. The full stack wins — training and inference improvements stack.
04/04
Independent · GTM Agent

GTM - Agent.

An indie-game go-to-market agent: four-module research pipeline, chat edits and cascade updates.
Type Independent
Role Agent System Design
Period 2026.04 — 06
Problem → Build

GTM Agent turns a one-page game brief into a structured four-module market analysis: Competitive Landscape, Audience Overview, Positioning Matrix and SWOT. A user can edit one field, regenerate a module, or trigger downstream cascade updates through chat.

Architecture
FIG. 04a
DAG generation pipeline × conversational cascade updates
pipeline waves input.md game brief COMPETITIVE Steam · SteamSpy · IGDB AUDIENCE segments · tagging POSITIONING SWOT THREE-COLUMN UI Tier 4 frontend conversational agent CHAT single entrypoint CASCADE UPDATE edit module · regenerate downstream VERIFY schema · grounding · judge BENCHMARKS 22 isolated cases
The core is a conversational GTM system: generation runs in DAG waves, CL → AO → PM ∥ SWOT; edits update the target module first and regenerate only its downstream dependents. FastAPI exposes /api/chat as the single entrypoint, the frontend shows input, chat and structured output in three columns, and evals check schema, grounding and judge quality.
§ 04 · Elsewhere

Away from the terminal, the world is worth exploring. Bring a camera.

Tromsø, Norway
Tromsø · NO
Plaza de España, Seville
Sevilla · ES
Notre-Dame, Paris
Paris · FR
Seine, Paris
Paris · FR
Barcelona beach
Barcelona · ES
Florence, Italy
Firenze · IT
Hyde Park, London
London · UK
§ 05 · Get in touch

Let's talk about reliable AI systems.

Open to AI engineering & research roles — agent systems, reliable LLM pipelines, interpretability. Based in London, willing to relocate.